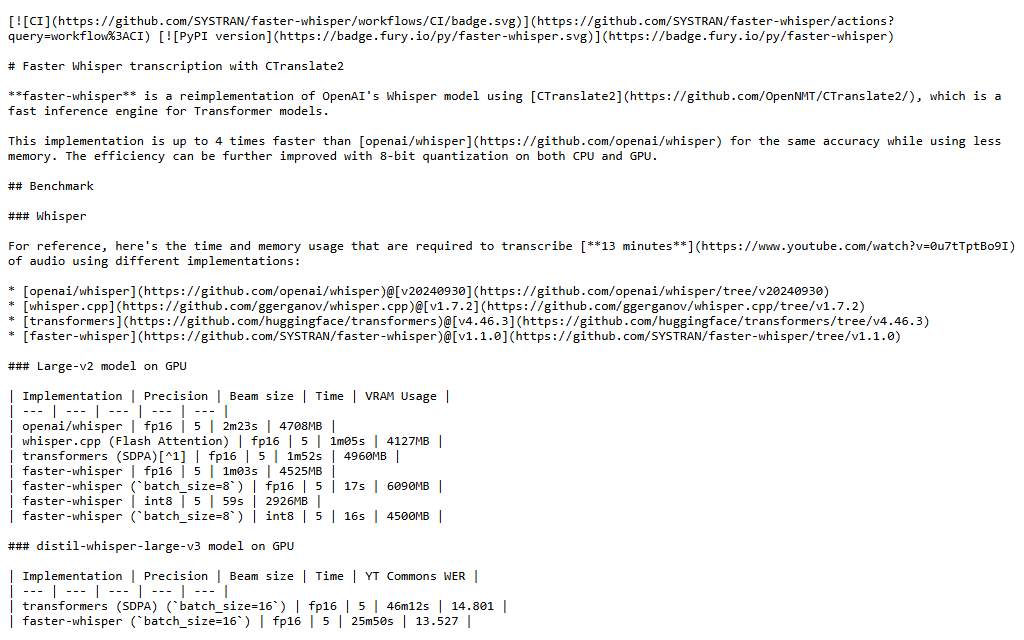
Whisper transcription implementation using CTranslate2 for optimized local inference.
The implementation uses CTranslate2 and documents GPU/CPU execution and quantization options. Benchmark results depend on the model, decoding settings and hardware.